 The SemOps Manual
3. Across the boundary: peers and supply chains
Part I — Why this is hard
Everything in Chapter 2 assumed a shared employer: one budget, one CI system, and, in the end, someone senior enough to settle an argument. Cross out those three assumptions and you have the cross-enterprise case, which is where semantic technology is simultaneously most valuable and most likely to fail.
It is most valuable because shared meaning across organisations cannot be achieved by a shared database; nobody will accept one. It is most likely to fail because every enforcement mechanism SemOps relies on stops at the company boundary. You cannot fail someone else's build.
3.1 What changes at the boundary
| Inside one enterprise | Across enterprises |
|---|---|
| One CI system can gate every change | You cannot gate a partner's pipeline; you can detect, notify, and refuse what they submit |
| A senior owner can settle a definition dispute | No shared authority: disputes are settled by negotiation or by power |
| Breaking changes can be fixed downstream by the same team | Downstream is someone else's backlog, with its own priorities |
| Cost of coordination is internal overhead | Cost of coordination is a commercial term someone must agree to pay |
| Sharing a model is uncontroversial | A model can reveal commercially sensitive structure |
| Capability is roughly uniform | Partners range from a semantics team to a spreadsheet and one IT contractor |
The last row is the one most often missed, and it dominates supply-chain work.
3.2 Three topologies, three different problems
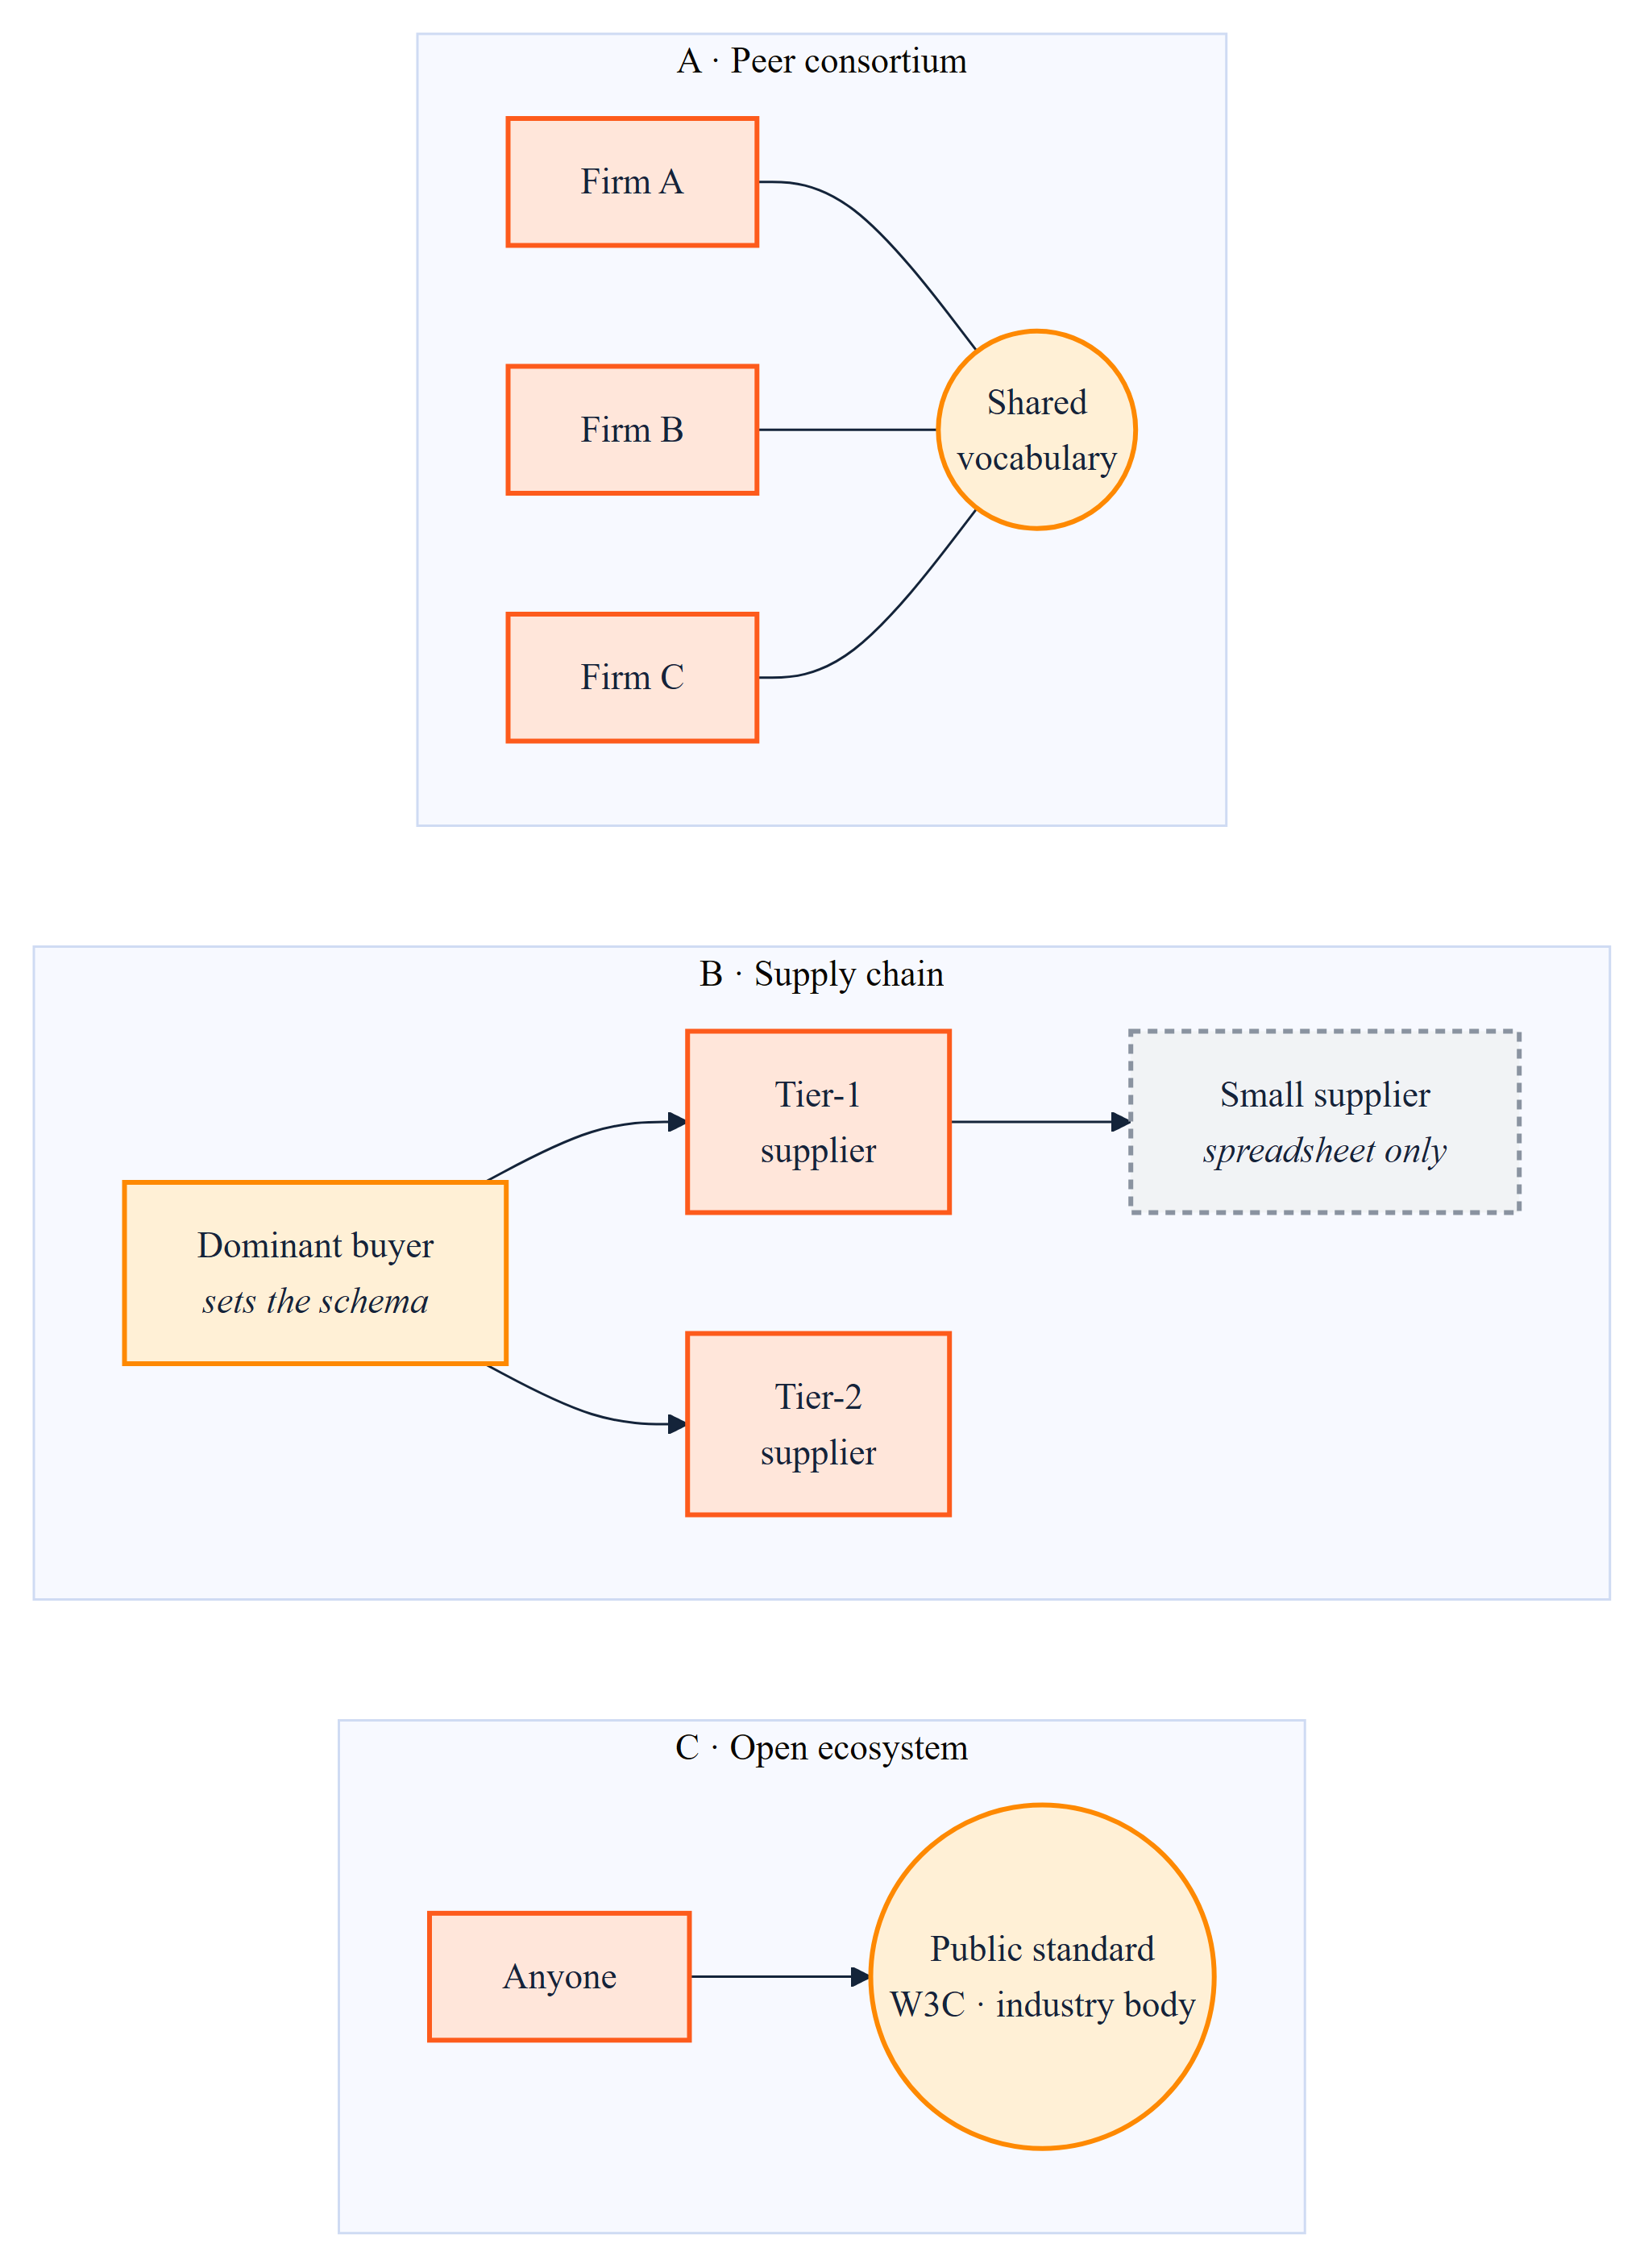
A. Peer consortium: the coordination problem
Competitors or near-peers agree a shared vocabulary: trade associations, regulatory reporting groups, interbank messaging, research consortia.
The hard parts are not technical:
- Nobody can compel anyone. Progress is by consensus, which means the model drifts towards the union of everyone's requirements and the intersection of everyone's willingness to constrain. Consortium ontologies are characteristically under-constrained: everything is optional, because making anything mandatory requires unanimity.
- Commercial sensitivity has a modelling shadow. How you model your customer segmentation reveals your customer segmentation. Members will decline to model the very areas where alignment would be most valuable, and will not always say that is why.
- Competition-law caution is real, and worth taking seriously rather than routing around. Legal review of a shared model in a concentrated market is a legitimate step, not obstruction.
- Release cadence is set by the slowest member, because a change nobody has implemented is not a change.
What works: a deliberately small mandatory core, with extension points. Publish the core with real constraints; let each member extend in their own namespace. This is exactly the pattern Part III uses at company scale: import the shared vocabulary, own your extensions, and check only what you own (Chapter 9).
There is now a second answer to the commercial-sensitivity problem, and it is worth knowing even though the component is young. A store that enforces access policy at the index scan can share a graph with a member while withholding particular predicates or classified graphs from them, and the policy holds for every query the member could write, aggregates and negations included. A member can then contribute to a shared graph without contributing their segmentation to their competitors (Chapter 13 §13.2).
B. Supply chain: the capability-asymmetry problem
One organisation has the leverage to mandate a schema: a large manufacturer, a retailer, a public body. Compliance is a condition of doing business, so adoption is not the problem.
The problems are:
- Capability asymmetry. A tier-1 supplier may have a data team. Their sub-supplier has a spreadsheet and a part-time IT contractor. A mandate that assumes RDF fluency does not produce compliance; it produces a cottage industry of consultants filling in forms on suppliers' behalf, and the data quality that implies.
- The mandate arrives without the tooling. "Send us this in the standard format" is not an ask, it is a project, and the cost lands on the party least able to absorb it.
- Verification is one-directional. The buyer validates what arrives. The supplier gets a rejection with no way to test in advance, so the loop is: send, get rejected, guess, resend.
What works: give the supplier the gate. The single highest-leverage intervention in supply-chain semantics is publishing the validation as something the supplier can run themselves, before submitting. From Part III's toolchain:
- Publish your SHACL shapes and check registry as files, not as prose in a PDF. The suite reads a registry directory from
--registry/--shapes/--sparql, so a shared registry is a distributable artefact (Chapter 8). - Accept CSV, or Parquet. Most of the supply chain has a spreadsheet, and the triplification path (Chapter 10) means the supplier never authors RDF at all. They produce the tabular extract they already have, and the mapping is yours to own and version. If you publish the mapping as an OTTR template library, a capable supplier can even instantiate it themselves.
- Ship the check as something that needs nothing installed. The VS Code extension runs its checks in WebAssembly, with no Python or Java. The SHACL engine and the triplifier each come as a single binary from their GitHub releases, with published checksums, and as a
pip installfor anyone with Python. For a small supplier that is the difference between "we can run this" and "we need to procure something".
That last point deserves emphasis: the runtime dependency is a governance decision. Mandating a validation step that requires a JVM excludes a class of suppliers from self-service compliance as surely as mandating a language they do not speak.
C. Open ecosystem: the stability problem
You depend on a public vocabulary you do not control: FOAF, the W3C Organization Ontology, schema.org, an industry standard, an upper ontology such as gist.
Here the risk inverts. You are not coordinating; you are exposed. The vocabulary may change, stagnate, or turn out to encode conventions that break your tooling in ways nobody documented.
The classic case is FOAF, which deliberately declares foaf:name with rdfs:domain owl:Thing, an intentional "usable on anything" convention. A conformance checker that walks asserted rdfs:subClassOf edges does not know that every class is implicitly a subtype of owl:Thing under OWL semantics, because that is an axiomatic fact rather than an ordinary triple. Unless the checker is taught the convention, the result is a domain "violation" on every foaf:name triple in otherwise perfect data. (The suite has been taught it: on this manual's fixture it reports nothing about foaf:name. A check you write yourself may not have been.) gist makes a related choice more widely, leaving most of its properties with no domain or range at all, for the good reason given in Chapter 2 §2.3.
Nobody is at fault. The vocabulary is behaving as designed, the checker is behaving as designed, and the finding is still wrong. Depending on a public vocabulary means inheriting its conventions, including the ones that were never written down. Budget for discovering them the hard way, and keep a fixture for each one you discover.
3.3 The cross-boundary release problem
Inside one enterprise, a breaking ontology change is manageable: detect it, find the affected queries, fix them, ship together (Chapter 12 does all three, and the last one automatically).
Across a boundary, the same change is a negotiation with a lead time. You cannot auto-repair a partner's queries; you often do not know they exist.
The protocol that works looks like this:
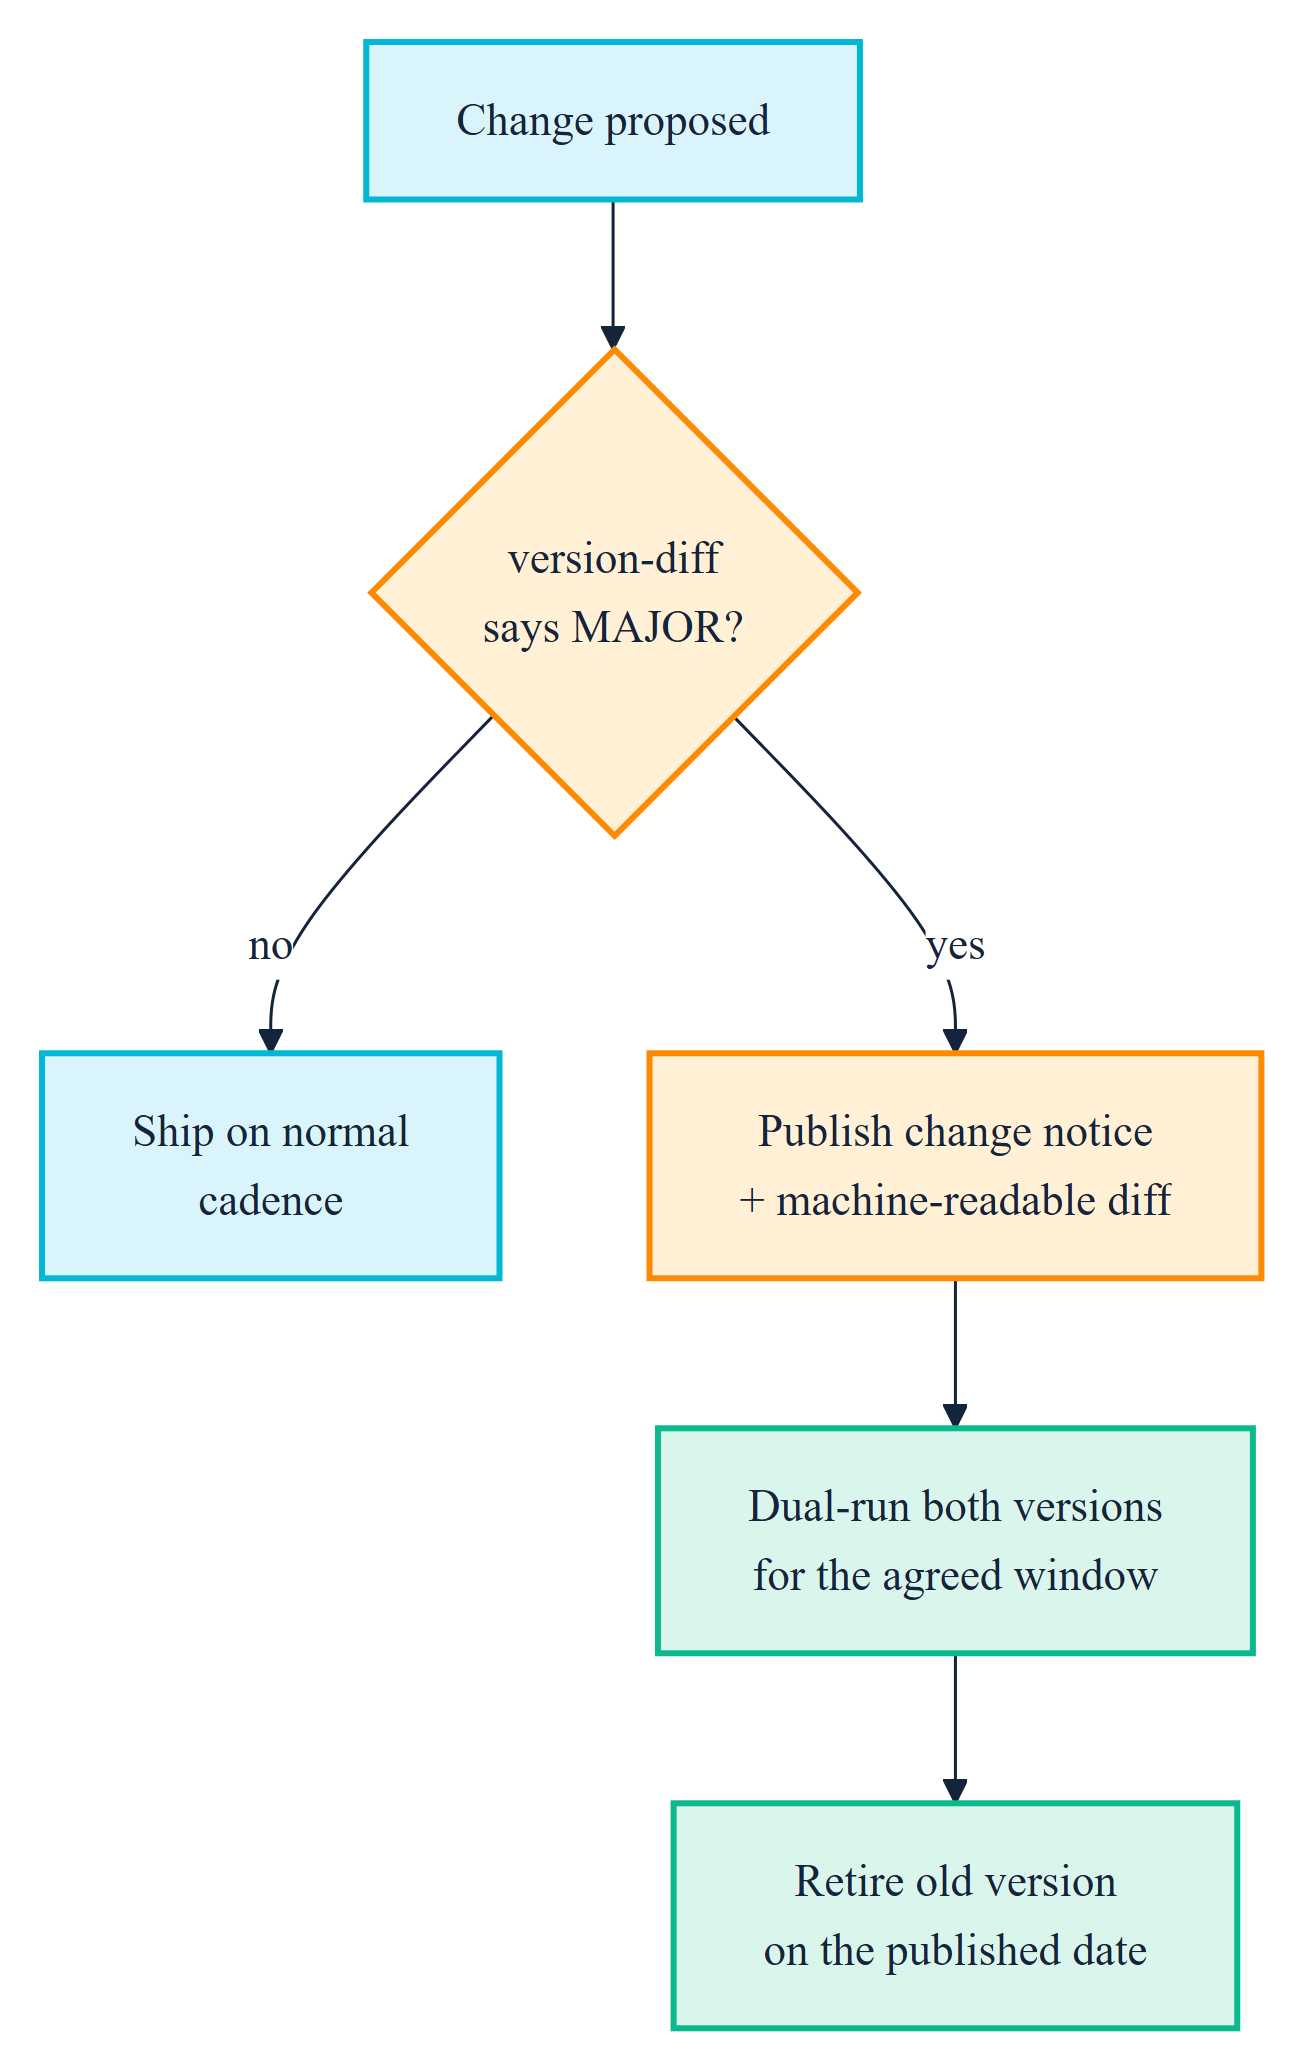
Two things make this workable rather than aspirational.
The bump decision must be evidence-based, not a judgement call. version-diff classifies a change by inspecting what actually happened to the axioms: a removed class is MAJOR whatever the author intended. In Chapter 12 it returns MAJOR for the fixture's release on the evidence of one removed class, while still reporting the additive changes as minor. Across a boundary this matters enormously, because "is this breaking?" stops being a conversation and becomes a command whose output both parties can run.
The change notice should carry the machine-readable diff, not just prose. version-diff --json writes diff.json alongside the human-readable text. A partner can then diff programmatically rather than reading your release notes and hoping.
Migration annotations are a cross-boundary contract
When you rename a term, leave a tombstone: an annotation in the new version saying where the old term went.
acme:Engineer owl:equivalentClass acme:SoftwareEngineer .Earlier editions of this manual told you that the suite's rename detection read this in one direction only, from the retiring IRI to its replacement, and that writing it the other way would silently drop confidence. That was wrong. The suite reads owl:equivalentClass as the symmetric statement it is, at full confidence either way (Chapter 12 §12.3).
I would still write it from the retiring IRI, and the boundary is the reason. Your tooling reads both directions. Your partner's may not. A tombstone written from the old term to the new one is the direction every tool agrees on, it reads naturally as "this went there", and it is the only direction that works if anyone in the chain uses dcterms:isReplacedBy, whose meaning is the direction. Inside one company, getting this wrong costs an afternoon. Across a boundary it is the difference between a partner's tooling identifying the replacement automatically and a human reading a PDF.
3.4 Trust, provenance and attribution
Once data crosses an organisational boundary, "who said this?" becomes as important as "what does it say?", and it is a question RDF is unusually well equipped to answer, provided someone decided to answer it.
Think about how provenance usually works. A document's metadata lives somewhere else: a catalogue record, a spreadsheet of submissions, an email thread. To find out who sent a figure you lift the pen and go and look. In a graph, the provenance can be more graph, on the same plane as the data it describes, and you can follow it without lifting the pen. Metadata is just data somebody decided to keep next to the data. That is the approach to take across a boundary:
- Keep each partner's contribution in its own named graph. This is the single decision that most improves cross-enterprise operability, and it is nearly free at ingest time and nearly impossible to retrofit. tarka's
--post --graphmakes it the default path; the suite's live-store checking is named-graph aware because this is the expected topology (Chapter 13). - Do not merge on ingest. A merged graph cannot answer "which supplier asserted this?", and that is the question the incident review will ask.
- Record the conformance verdict, not just the data. "This batch passed the agreed shapes at version 2.1 on this date" is the artefact that resolves disputes.
- Consider recording provenance per statement. RDF 1.2 can make a statement about a statement directly, with a triple term, so "which submission added this?" can be asked of the statement itself rather than looked up somewhere else. It is the Möbius strip again: the provenance lives on the same surface as the claim.
Note the limit of named graphs alone. They give you provenance and lifecycle, not scoped validation: the SHACL engine validates the union of whatever it is given, so checking one partner's contribution against one partner's contract means extracting that graph and validating it on its own, which is what the suite's live-store manifest does (Chapter 13 §13.1).
3.5 Where this leaves the practice
The cross-boundary case does not need a different toolchain. It needs the same toolchain with a few shifts of emphasis:
| Inside | Across |
|---|---|
| The gate fails the build | The gate produces a notice the other party can act on |
| Repairs are applied automatically | Repairs are published as patches for the other party to apply |
| Ownership is a role | Ownership is a contract term |
| Checks scoped to what we own | Checks scoped to what we own and published so partners can run them too |
| Everyone sees everything | Each party sees what policy at the scan allows (early) |
Most of the right-hand column is a matter of who receives the output, which is why the mechanics in Part III transfer largely unchanged. The failure mode is assuming the left-hand column's enforcement model still applies: building a beautiful gate, and discovering it has no jurisdiction.
One last design lesson, which I took from the triplifier rather than from a standards body. tarka loads into a store by speaking the SPARQL Graph Store Protocol rather than by linking any particular store in, on the grounds that the protocol reaches every store alike. Across a boundary, speak the protocol, not the product. Your partner chose their store before they met you.